Accelerator hardware refers to specialized compute devices—GPUs, TPUs, IPUs, FPGAs, custom ASICs and NPUs—that off-load or augment workloads formerly handled by CPUs, achieving higher throughput per watt and per dollar by tailoring micro-architecture, memory, and interconnect specifically for matrix math and data-parallel operations common in AI and HPC.
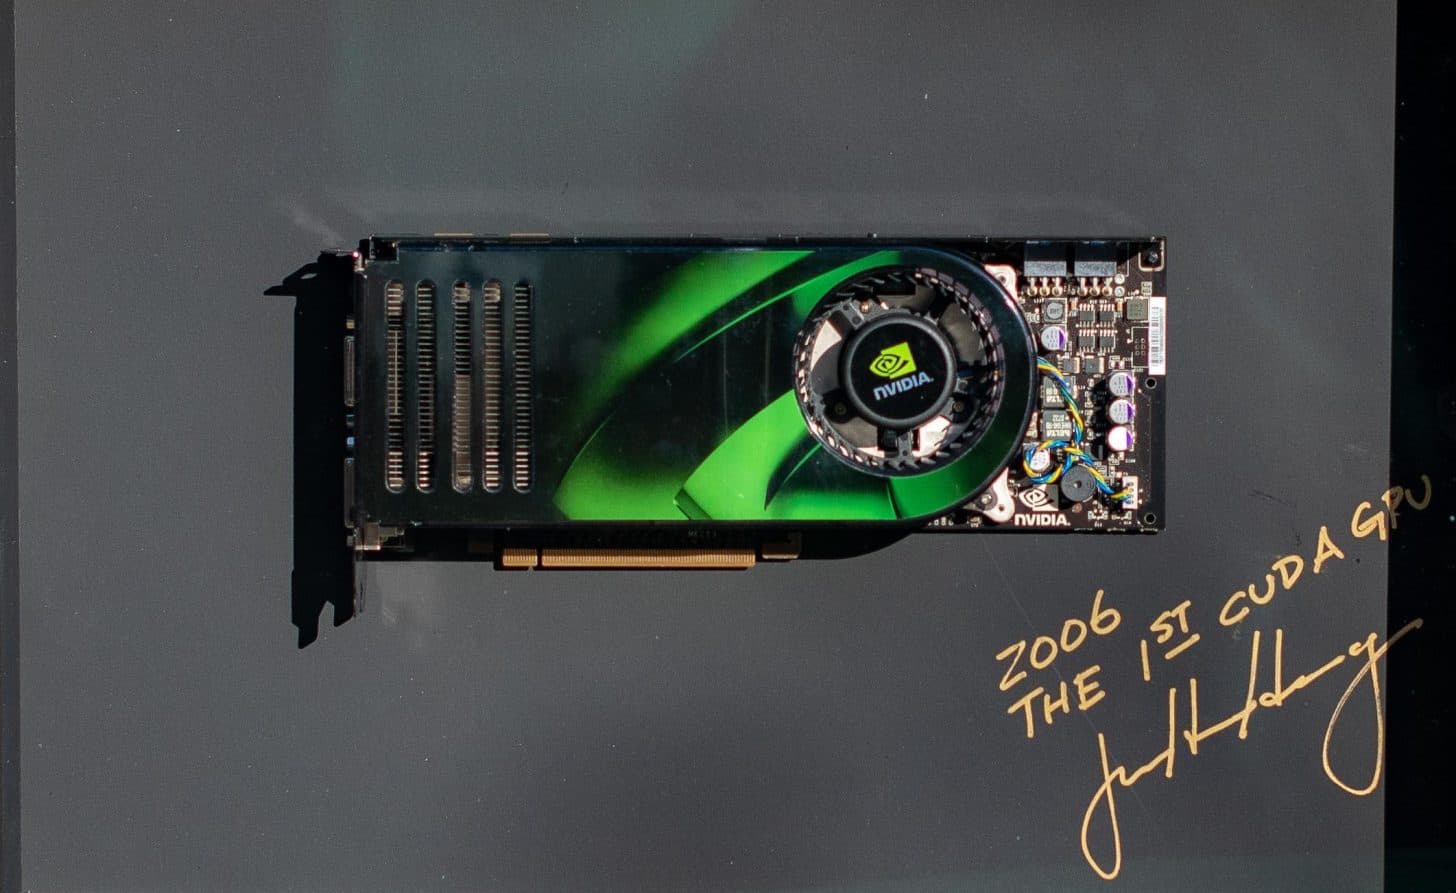
GPUs such as NVIDIA's A100 add tensor cores and high-bandwidth memory for mixed-precision math1, while ASIC families like Google's TPU v5p rely on systolic arrays and optical circuit-switch fabrics to scale to thousands of chips in a single pod2.
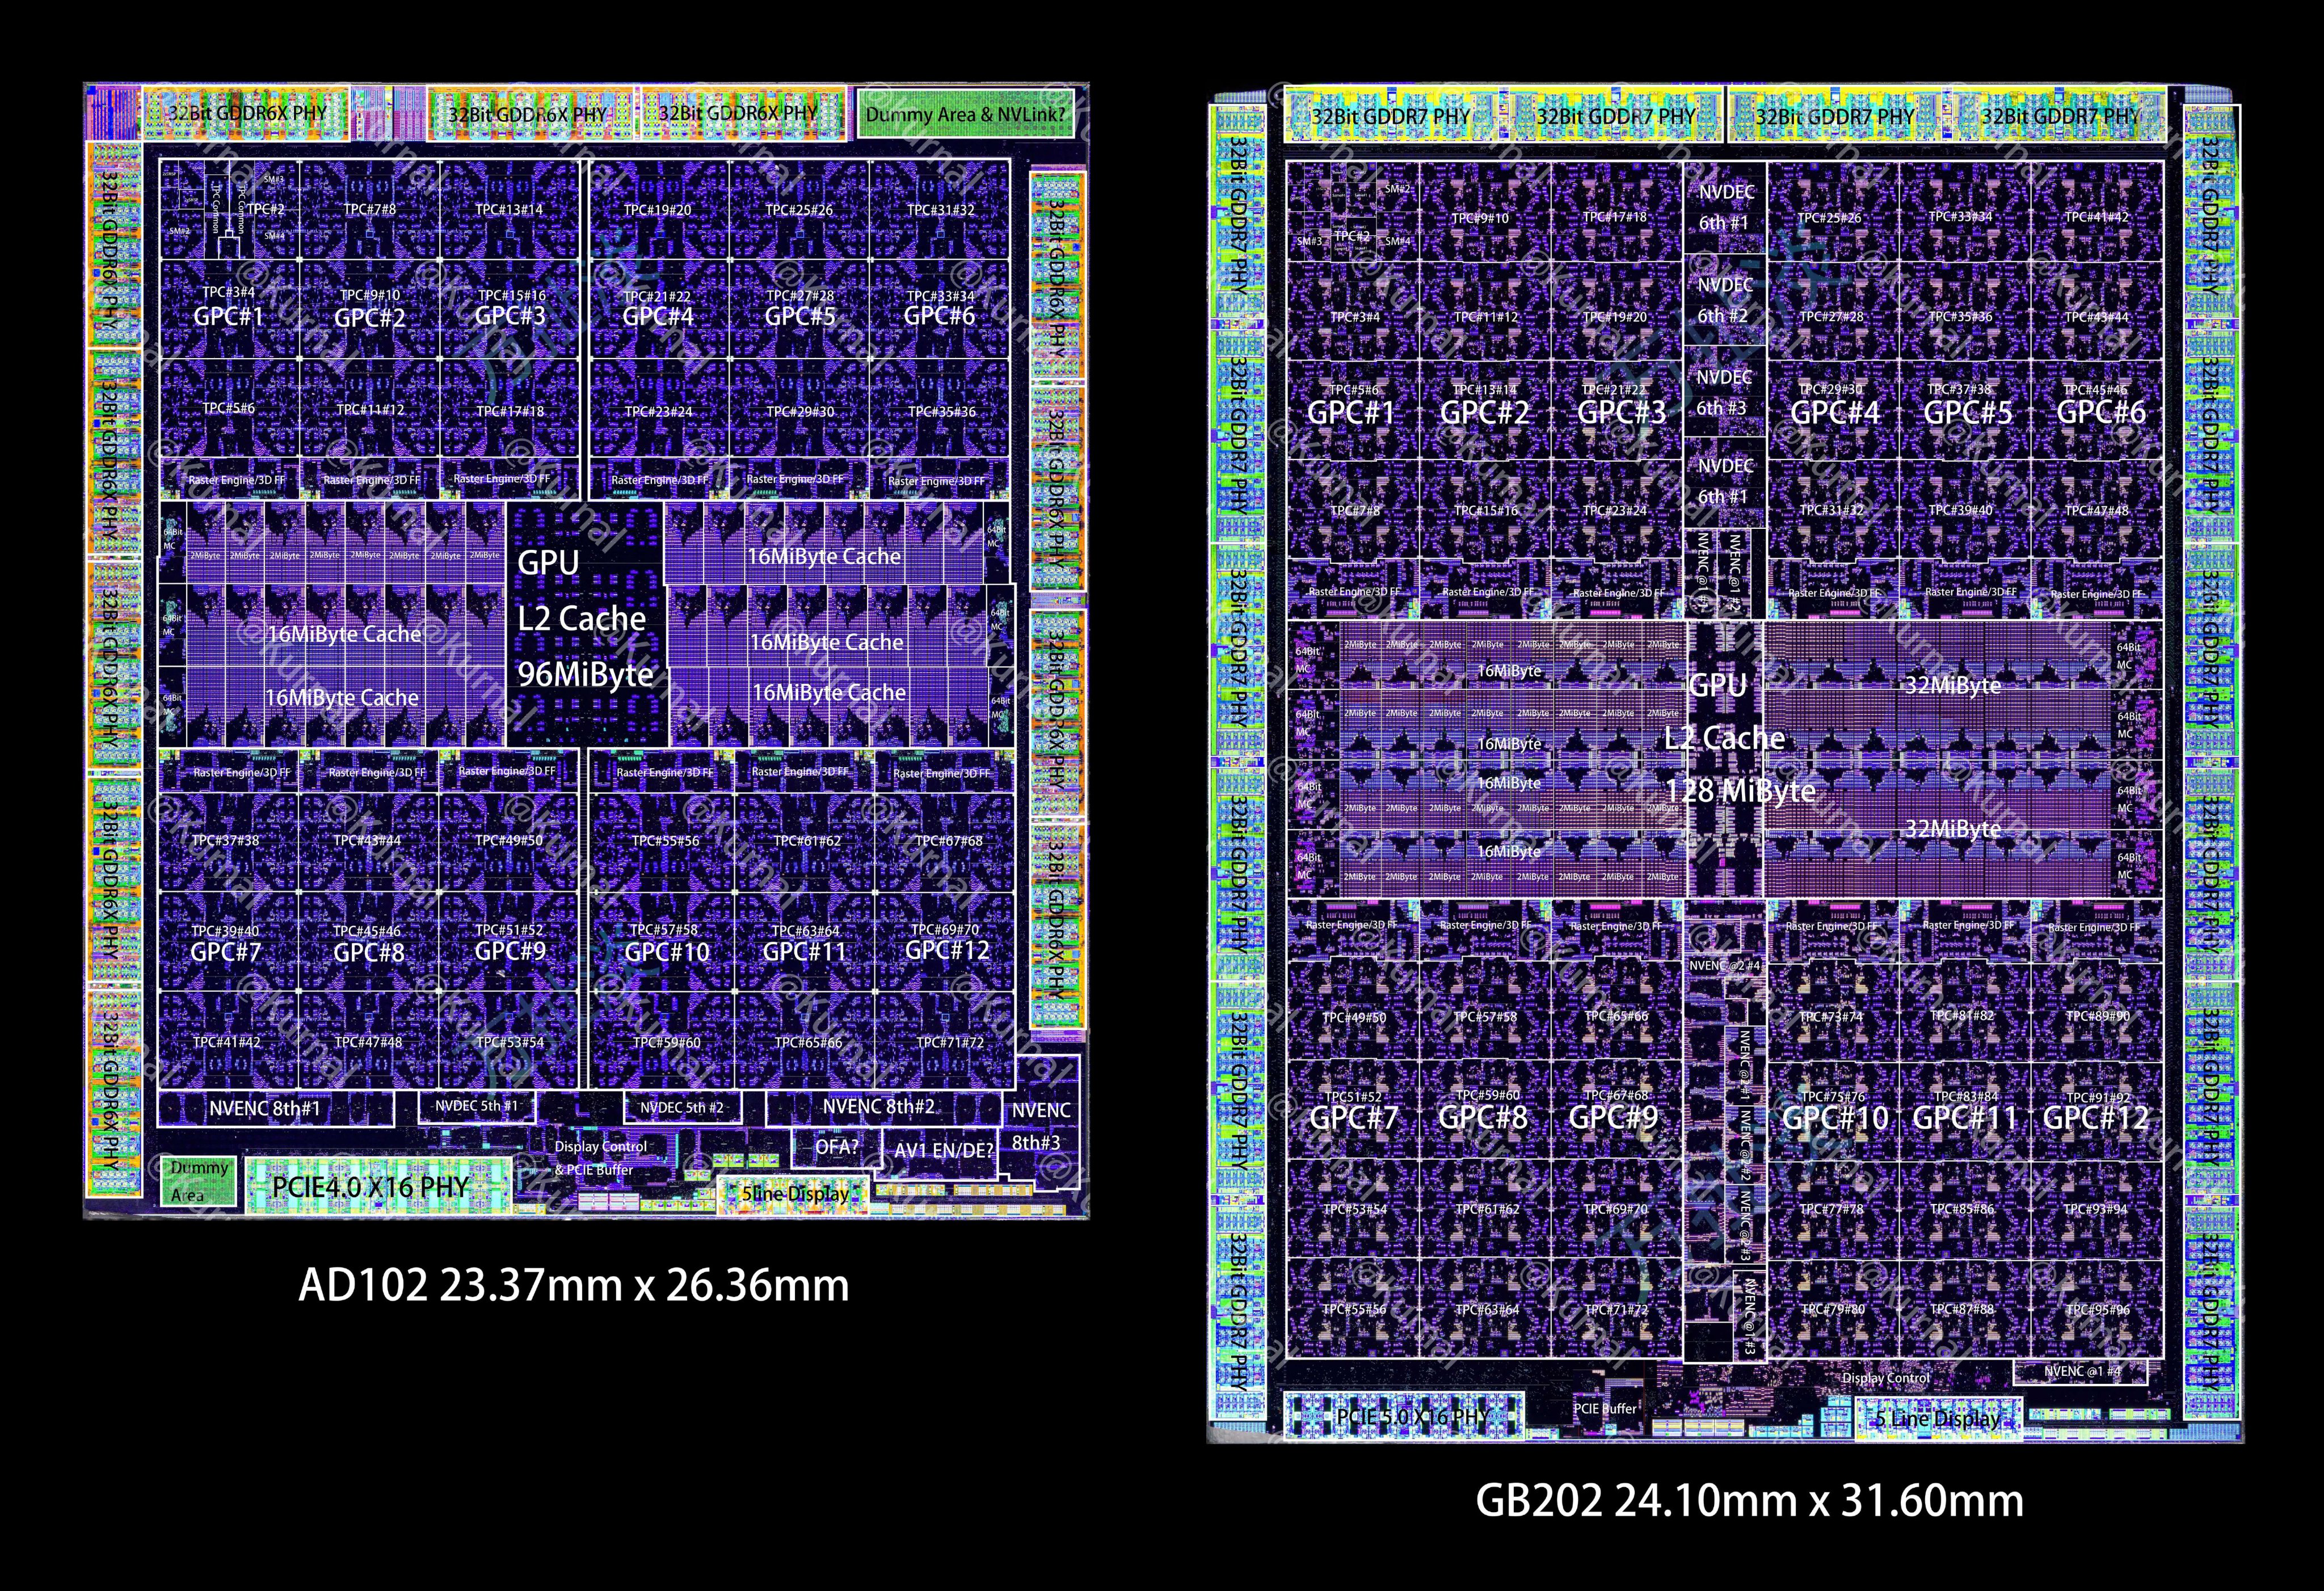
Start-ups and incumbents keep expanding the landscape with Intel's Gaudi23, AMD's MI350 series4, Graphcore's MK2 IPU5, edge NPUs in mobile SoCs6, and customer-specific ASIC programs from firms such as Marvell7.
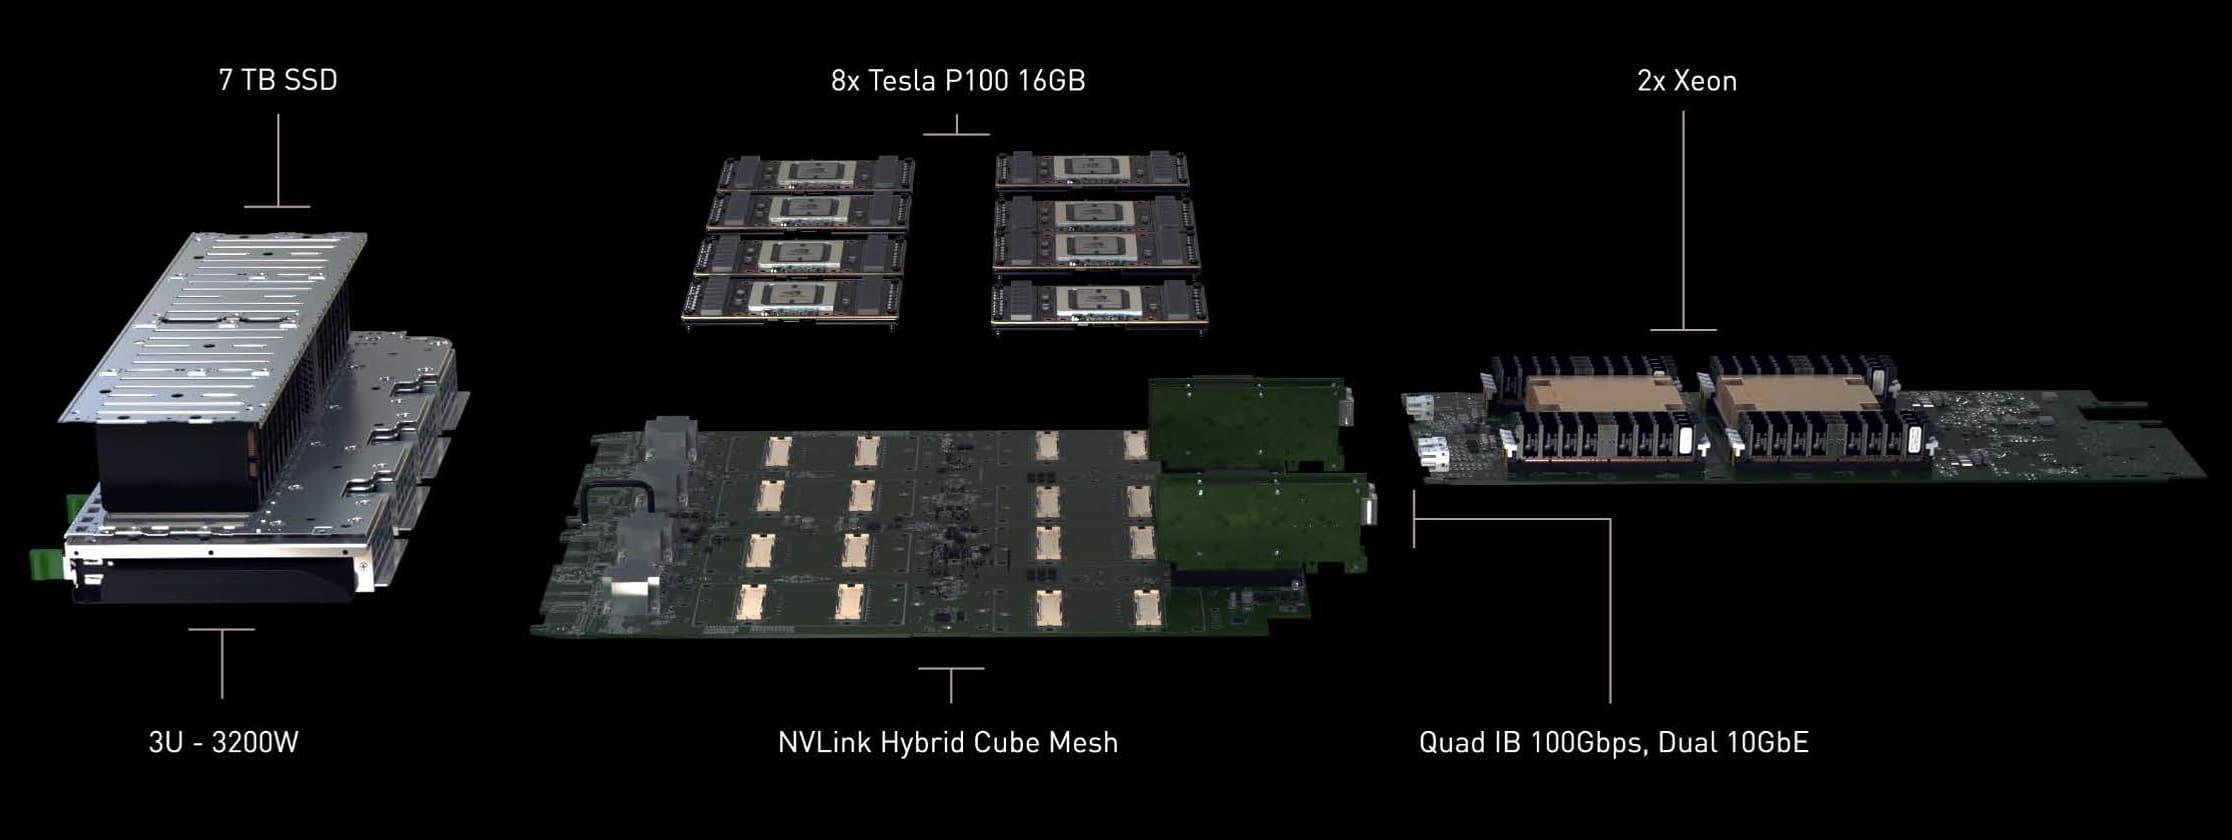
Together these devices drive today's large language model training, real-time inference, and data-center evolution by providing petaflop-class dense compute, terabytes-per-second memory bandwidth and low-latency fabrics at rack scale.
Definition and Scope
A hardware accelerator is any processor class built to execute a narrowly defined workload far faster or more efficiently than a general-purpose CPU, often by exploiting massive fixed-function or SIMD/MIMD parallelism8. Typical targets include dense linear algebra, graph traversal, cryptography, compression and video codecs. Contemporary AI accelerators focus on fused multiply-add (FMA) and convolution kernels in low-precision formats (FP8, BF16, INT8, FP4/6) to improve statistical efficiency and energy use9.
Architectural Building Blocks
Compute Tiles
- Tensor / Matrix Engines — NVIDIA's third-generation tensor cores deliver sparse, mixed-precision FMA inside each streaming multiprocessor10, while Google's TPU v4 packs MXUs that operate in a systolic array pattern to keep data stationary and limit DRAM traffic11.
- Vector & Scalar Units — RISC-V vector extensions allow general CPUs to accelerate data-parallel Java workloads without external devices12.
- Many-core Meshes — Graphcore's IPU integrates 1,472 independent cores plus 900 MB on-die SRAM so models can stay on-chip, reducing DRAM latency13.
Memory Hierarchy
HBM3E on AMD's MI350 delivers 288 GB capacity and 8 TB/s bandwidth, critical for large transformer contexts without gradient checkpointing14. On-chip scratchpads and register files, as modeled in Google's Neurometer framework, sharply influence power-area trade-offs during floor-planning15.
Interconnects & Packaging
Next-gen parts add chiplets and advanced packaging: AMD's MI350 uses a 3 nm CDNA4 compute tile with 12 Hi HBM stacks on an organic substrate, while Marvell's custom ASIC program employs 112 G XSR die-to-die links and 240 Tb/s parallel fabric for multi-chip systems16. At rack scale, TPU pods connect 4,096 chips via optical circuit switches to form an exa-scale cluster17.
Data Types & Sparsity
Support for FP8, FP6 and FP4 enables tighter quantization with minimal accuracy loss; AMD reports 40 PFLOP FP4 peak per MI350X card18. NVIDIA enforces 2:4 structured sparsity in A100 tensor cores to double effective throughput with software-assisted pruning19.
Major Categories and Exemplars
Performance Metrics
Practical comparison requires more than peak TOPS. Key indicators include:
- Throughput/Watt — TPU v4 improves per-chip performance/Watt by 2.7× over TPU v328.
- Tokens-per-Dollar — AMD claims MI355X delivers 40 % more tokens per dollar than NVIDIA B200 in large-language-model serving29.
- Latency at 99th Percentile — Vital for online inference; Intel reports Gaudi2 meets 7 ms BERT-Large SLA at batch-size = 128 without tuning30.
Modeling frameworks such as Neurometer predict power and area within 10 % of silicon for new tensor-array designs, assisting architects in early trade studies31.
Programming Models and Software Stacks
- CUDA / cuBLAS / Triton for NVIDIA GPUs.
- ROCm and MIGraphX for AMD Instinct.
- XLA and JAX dominate TPU compilation paths, while TPU VMs expose PCIe for hostless execution32.
- SynapseAI maps graphs onto Gaudi's ten-port RDMA network engine33.
- Poplar SDK expresses fine-grained parallelism on Graphcore devices34.
- OpenCL, HLS, and DPC++ target FPGA fabrics for hardware-software co-design35.
Design Trade-offs
- Flexibility vs. Efficiency — GPUs run a broad workload surface but trail ASICs in perf/W; FPGAs re-balance after new algorithm discoveries.
- Memory Capacity vs. Bandwidth — High-capacity HBM extends context length yet raises thermal density; on-chip SRAM in IPUs minimizes external traffic.
- Scale-Up vs. Scale-Out — TPU-pods favor enormous uniform clusters, whereas Gaudi-based racks expose Ethernet for commodity networking.
- Longevity vs. Time-to-Market — Marvell's custom ASIC service promises tape-out in under 18 months by reusing proven IP blocks36; FPGA designs can be redeployed overnight.
Current Trends (2025)
- Low-Precision Arithmetic — Industry acceleration toward FP4/FP6 widens compute density by ≥2× year-over-year37.
- Advanced Packaging & Chiplets — 3D stacking and die-to-die SERDES break reticle limits, visible in AMD's CDNA4 and Marvell's 3 nm portfolio38.
- Optical Interconnects — TPU v4's OCS fabric points to photonics as an emerging path to rack-scale bandwidth without power explosion39.
- Edge AI Boards — Developers compare Jetson Orin, Hailo-15 and RockChip for cost, supply chain and power constraints in embedded vision products40.
- Sustainability Metrics — AMD sets a 20× rack-scale efficiency target for 2030, aligning vendor roadmaps with datacenter carbon budgets41.
Key Workloads
Take-away for Practitioners
Selecting accelerator hardware involves matching numeric format, memory footprint, networking topology and software tooling to model size, latency budget and budgetary limits.
Benchmark beyond peak FLOPS — profile kernels, interconnect contention and compiler maturity on target devices. Keep an eye on low-precision progress and chiplet roadmaps, as they will shape the next design refresh cycle.